High-performance compute power
Designed for medical AI with a high-speed NVMe SSD array and generous VRAM, removing storage IO bottlenecks for consistently smooth AI inference
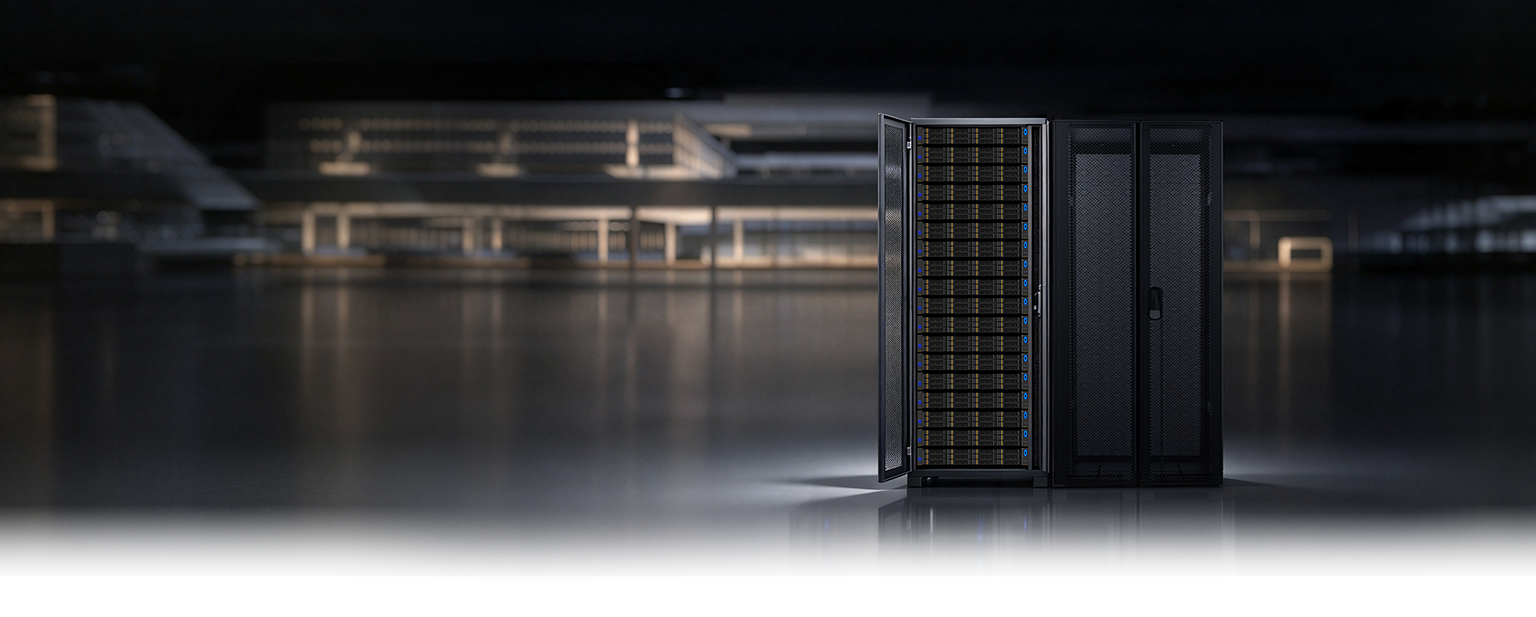
A compute power foundation built for medical AI inference, reliably supporting imaging reading and medical large-model workloads
Designed for medical AI with a high-speed NVMe SSD array and generous VRAM, removing storage IO bottlenecks for consistently smooth AI inference
Standard 2U rack-mount with fully pre-integrated hardware and software. No server-room retrofit required — rack, power on and connect is all it takes, dramatically reducing operations cost
Supports both single-node and cluster deployment. A single node suits small and mid-sized institutions; multiple nodes form a cluster that handles concurrent multi-department reading in tertiary hospitals through load balancing
A multi-node cluster architecture automatically shifts traffic on single-point failure, keeping core services such as emergency and radiology running 24/7 without interruption
Choose the deployment mode that fits your institution size and workload; compute power scales smoothly as your business evolves
One server carries the full chain of imaging AI, large models and storage, ready out of the box. Suited to lightweight needs such as primary hospitals and small enterprises: low cost and short lead time
Multi-server clustering plus load balancing delivers high-availability disaster recovery and concurrent access from multiple departments and systems. Suited to scale-out scenarios such as tertiary hospitals and regional centres, with elastic compute power scaling